Publishing open data has often been expensive for the wrong reason. The usual way to share a dataset is a service that answers queries: an API, a WMS or WFS server, an OGC API endpoint. Every question a user asks runs on the publisher's servers. A popular dataset means more servers, more operations and a bigger bill, paid by the one party that gets nothing back for each query. That imbalance is why so much open data ends up slow, rate-limited, or switched off.
Cloud-native formats turn this around. Instead of answering queries, the publisher puts files on object storage: Parquet and GeoParquet for tables, cloud-optimized GeoTIFFs and PMTiles for rasters and maps. Readers bring their own engine, download only the parts of the files they need, and do the computing themselves. Specifications such as Portolan build on this: a place's geospatial data published as cloud-native files, indexed by Apache Iceberg tables, with no query server at all.
That leaves two problems. The files sit in one place, so a reader on the other side of the world waits for every request to cross the distance. And the publisher still pays for every byte that leaves the bucket.
Open data on LakehouseBox
LakehouseBox stores Apache Iceberg catalogs and files behind an S3-compatible API. Any catalog can be made public, and a public catalog is served from a CDN: both the catalog, which tells a reader what tables exist and where their files are, and the files themselves. Anyone can attach it by name, with no account, no key and no secret:
INSTALL iceberg; LOAD iceberg; INSTALL httpfs; LOAD httpfs;
ATTACH 'commons/pubdata' AS pubdata (TYPE iceberg, ENDPOINT 'https://public-catalog.lakehousebox.com', AUTHORIZATION_TYPE 'none');
SELECT * FROM pubdata.weather.forecast LIMIT 10;
commons/pubdata is the catalog of open datasets we maintain (eighteen of them: weather, places, boundaries, holidays, air quality and more); any organisation's public catalog attaches the same way, as <handle>/<catalog>.
With and without a CDN
An analytical query is not one request but hundreds. DuckDB reads a table's metadata, then the parts of the Parquet files it needs, in many small ranged reads: scanning our 7.3-million-row places table took 1,147 of them. Straight from our storage in Nuremberg, each of those requests travels there and back. Through the CDN, it stops at a location next to the reader.
We ran the same eight queries from five places at once, a laptop in Madrid and small cloud VMs in Frankfurt, Ashburn (US East), Singapore and Sydney, each in a new DuckDB process with no account, both ways.
Through the CDN, the answer time barely depends on where the reader is: the scan takes 4 to 6 seconds in all five places. Straight from Nuremberg, it grows with the distance, to 221 seconds from Sydney. Across all eight queries (geometric mean of the speedups):
| reader | straight from Nuremberg → through the CDN |
|---|---|
| Frankfurt, next door | 1.3× faster |
| Madrid, home fibre | 3.5× faster |
| Ashburn, US East | 4.7× faster |
| Singapore | 9.4× faster |
| Sydney | 11.0× faster |
All eight queries, from all five places
Median wall seconds of a brand-new process (start, extensions, attach, answer), straight from Nuremberg → attached through the CDN:
| query | Madrid | Frankfurt | Ashburn | Singapore | Sydney |
|---|---|---|---|---|---|
| Count 249 countries | 1.42 → 0.31 | 1.11 → 0.94 | 3.48 → 1.17 | 7.33 → 1.18 | 9.02 → 1.36 |
| Earthquakes ≥ M7.5 since 2020 | 2.11 → 0.40 | 1.31 → 1.04 | 4.88 → 1.13 | 10.77 → 1.03 | 13.50 → 1.20 |
| 3.3M NYC taxi trips joined to zones | 3.83 → 0.72 | 1.88 → 1.32 | 8.55 → 1.78 | 19.58 → 2.57 | 24.39 → 2.39 |
| Pharmacies among 7.3M places | 7.45 → 4.23 | 8.23 → 5.00 | 71.59 → 5.30 | 175.95 → 5.31 | 221.28 → 5.96 |
| Air quality readings joined to stations | 5.48 → 1.75 | 3.77 → 2.27 | 26.11 → 2.70 | 62.96 → 3.31 | 78.93 → 3.51 |
| Point in polygon (460 MB) | 8.26 → 5.44 | 5.67 → 5.27 | 10.21 → 5.31 | 19.51 → 5.92 | 23.54 → 5.81 |
| Rail in a Paris bounding box | 2.57 → 0.58 | 1.94 → 1.69 | 6.15 → 2.01 | 12.85 → 2.06 | 15.85 → 2.54 |
| Same, on the bounding-box columns | 2.42 → 0.47 | 1.28 → 1.01 | 5.39 → 1.13 | 12.13 → 1.23 | 15.12 → 1.11 |
Five runs per query and path, the paths interleaved; the median of runs 2–5. Every path returned the same rows on every machine. The VMs are GCE e2-standard-2 (2 vCPU) and the laptop has 14 cores, which is why Madrid can beat Frankfurt. All five ran at the same time on 18 October 2026.
Why Iceberg suits a CDN
An Iceberg table never changes a file in place. Every change adds files: new data files, a new manifest and a new metadata file that points at them; compaction writes new, larger files; old files are only deleted later, when no snapshot needs them. A file, once written under its name, stays exactly the same until it is removed. That is what lets the CDN keep a table's files for a year without ever serving a stale one.
What it must not cache for long is the small part that says which version is current: the catalog's answers. Those are kept for under a minute, so a reader sees a new snapshot within a minute of its commit, and gets the large bytes from nearby.
The one cost is the first reader at each CDN location. The first time a file is requested there, the CDN fetches it from Nuremberg, and for some queries that first read is slower than going straight to the source: our 460 MB point-in-polygon query took 81 s through the CDN the first time from Sydney, against 24 s directly, and 5.3 to 7.7 s on every run after. For public data, read again and again by many people, that is the right trade.
Why not just a public bucket?
Iceberg is files, so the obvious alternative is to put them in a public bucket on Google Cloud Storage or Amazon S3. We tried it: the same tables, copied to a public bucket in Frankfurt on each cloud, read with no key by the same eight queries on 19 October 2026. No reader read a bucket on its own cloud: Google Cloud VMs read the S3 bucket, AWS VMs read the Google Cloud Storage one.
| Reader | Public S3 bucket | Public Cloud Storage bucket |
|---|---|---|
| Frankfurt | 1.2× slower | 1.3× slower |
| Madrid | 3.7× | 3.5× |
| US East | 4.8× | 6.6× |
| Singapore | 10.7× | 14.9× |
| Sydney | 11.3× | 27.3× |
Geometric mean over the queries, against attaching the same tables through LakehouseBox's CDN. The places scan from Sydney took 222 s from the S3 bucket and 537 s from the Cloud Storage one, against 5 s through the CDN. We stopped the runs early once the pattern was clear, so the Singapore and Sydney figures rest on fewer runs.
A bucket is one place, and every one of a query's hundreds of requests travels to it. A CDN in front of the bucket fixes most of that, and it can be cheap. But the bucket's files are not all alike. A file-based Iceberg table finds its current version through one small file, version-hint.text, which every commit overwrites. Cloud Storage serves a public object with a one-hour cache header by default, and Google's network keeps it. After we committed new rows to a table, a reader on AWS in Sydney was served the old pointer in every sample for the 36 minutes we kept watching. DuckDB on a laptop in Madrid returned the old row count 28 minutes after the commit, and once failed in the middle of a query because two reads of the same file came back with different versions.
Any CDN that only sees files faces the same choice: cache the pointer and readers see old tables, or don't and every query starts with a trip to the origin. LakehouseBox's CDN does not have to choose. The pointer is the catalog's answer, kept for under a minute; the files it points at never change, and are kept for good.
What publishing costs
LakehouseBox does not charge for egress. Whoever reads your public catalog, and however often, the reads cost you nothing, and a read the CDN answers from its cache never reaches our storage at all. What publishing costs depends on how much you store, never on how much it is used: one reader or a million, the same. Public catalogs get free storage today, 5 GB as soon as you publish and up to 50 GB for datasets we review.
That makes open data something a publisher can afford to keep running. And it does not have to be a static dump: Iceberg tables take new commits, so a dataset can be updated every day or every hour, and readers always get the current snapshot. LakehouseBox runs the table maintenance (compaction, snapshot expiry) in the background, so a table that keeps changing stays fast to read.
Publishing takes a few commands
Putting a dataset there is short work, for a person or for an agent. Our command-line tool, lhbox, creates a catalog, loads a CSV straight from a URL into an Iceberg table (the header and the column types are detected), describes it, and publishes it; anyone can attach it the moment it is public:
lhbox catalog create co2data
lhbox table import co2data.owid.co2 https://raw.githubusercontent.com/owid/co2-data/master/owid-co2-data.csv
lhbox table document co2data.owid.co2 --doc "CO2 emissions by country and year, Our World in Data"
lhbox catalog publish co2data --confirm co2data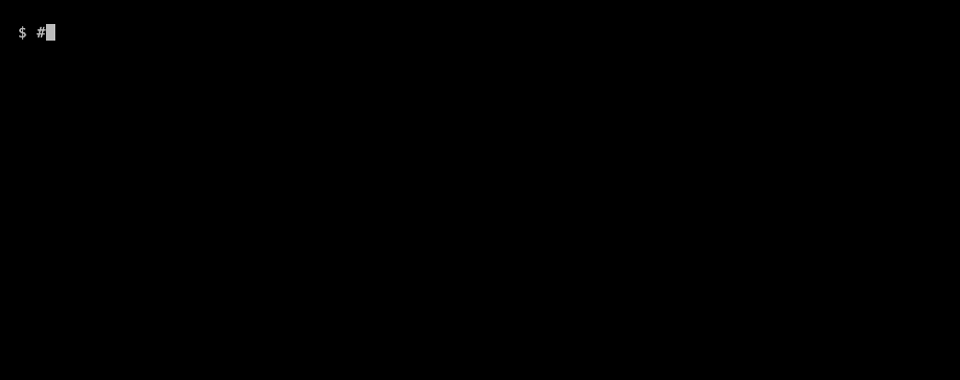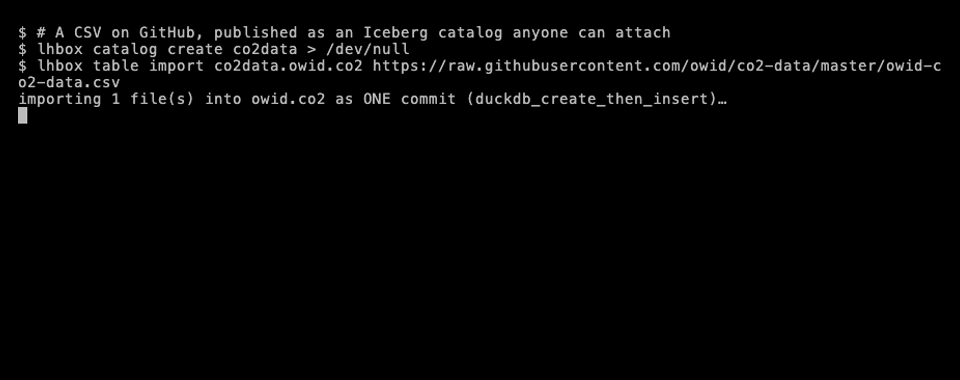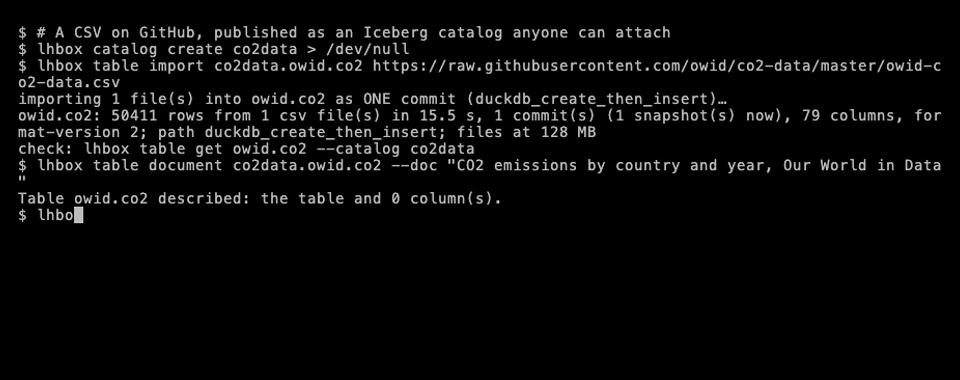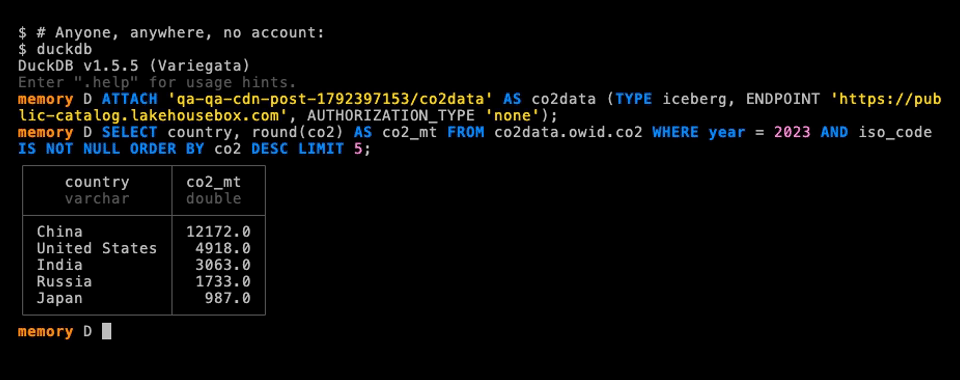
An agent with no account at all can start one step earlier: lhbox new gives it a catalog of its own that it can load straight away, and a person keeps it with lhbox claim, a link and a code, before it is published.
Attach open data like a database
Once data is published this way, it stops being a download and becomes a database you attach. Two ATTACH lines, two publishers, and from then on it is one SQL database: here our catalog of open datasets next to portolan/madrid, the City of Madrid's open data published by another organisation as a Portolan catalog. Madrid's neighbourhoods, with the unemployment rate the city publishes for each, against the places to eat out that Overture maps in each one:
INSTALL spatial; LOAD spatial;
ATTACH 'commons/pubdata' AS pubdata (TYPE iceberg, ENDPOINT 'https://public-catalog.lakehousebox.com', AUTHORIZATION_TYPE 'none');
ATTACH 'portolan/madrid' AS madrid  (TYPE iceberg, ENDPOINT 'https://public-catalog.lakehousebox.com', AUTHORIZATION_TYPE 'none');

SELECT b.barrio, b.unemployment_pct, count(*) AS places_to_eat
FROM madrid.v3.paro_barrios_crs84 b
JOIN pubdata.places.places p ON ST_Contains(b.geometry, p.geometry)
WHERE p.basic_category IN ('restaurant', 'casual_eatery', 'bar')
GROUP BY ALL ORDER BY places_to_eat DESC LIMIT 5;
┌─────────────┬──────────────────┬───────────────┐
│ barrio │ unemployment_pct │ places_to_eat │
├─────────────┼──────────────────┼───────────────┤
│ Universidad │ 6.61 │ 344 │
│ Justicia │ 6.23 │ 326 │
│ Palacio │ 7.45 │ 324 │
│ Embajadores │ 7.66 │ 288 │
│ Sol │ 6.51 │ 287 │
└─────────────┴──────────────────┴───────────────┘Two ATTACH lines and one query, with no account, in under 5 seconds from Madrid, both catalogs and the spatial join included; DuckDB read only the part of Overture's 7.3-million-row Europe-wide table that falls in Madrid. Neither publisher had to plan for this question, and the reader did not have to download anything first.
Hugging Face's faceberg explores the same idea for datasets on the Hugging Face Hub, exposing them as Iceberg tables behind a REST catalog. The commercial engines are not there yet: BigQuery and Databricks read Iceberg only through catalogs they federate with, not an arbitrary catalog on the internet; Snowflake can attach an outside Iceberg catalog, but only after its support team allows the storage endpoint for your account. As more of the industry embraces open table formats, we expect those walls to come down.
Built for agents
This is what excites us most. An agent asked a question does not need someone to have prepared a dataset for it: it can attach the catalogs that might hold the answer, look at what is inside, and query its way there, joining one publisher's tables with another's as it goes. That is the promise of Portolan, and the reason we think this changes how useful open data can be: a city's, an agency's or a researcher's data becomes something any agent can reach and combine on demand, not a file someone has to find, download and clean first.
For that, the agent has to understand what it is looking at, and a table name is rarely enough. So a catalog on LakehouseBox carries its own explanation at every level:
- Columns carry a description in the Iceberg schema itself: units, codes, what a null means, which other table a key joins. DuckDB shows them as soon as the catalog is attached (
duckdb_columns()); ourcountry_codereads "ISO 3166-1 alpha-2, upper case (joins reference.countries)". - Tables carry a description of their grain, source and freshness:
lhbox table document <table> --doc … --column name=…writes both, in one commit. - The catalog carries an
AGENTS.md: a briefing for agents on what the tables mean, how they join and what to watch out for, set withlhbox catalog agents-md --set AGENTS.md. It is public while the catalog is, and our MCP server returns it with the tables when an agent opens a public catalog. Ours forcommons/pubdatais 14 KB and tells an agent, for example, to filtersubdivision IS NULLbefore joining national holidays.
The data comes with its own manual, written for the reader most likely to open it next: an agent.
Beyond tables
Not all open data is tables. A geospatial dataset usually comes with rasters and tiles too: cloud-optimized GeoTIFFs, PMTiles. A public catalog on LakehouseBox can publish those files next to its tables, readable by anyone with no account; today they are served from our storage in Nuremberg. Serving them from the CDN as well is next on our list: those files can change in place, so they need a different caching rule than Iceberg's.
Try it
DuckDB 1.5.5 or newer, nothing else:
INSTALL iceberg; LOAD iceberg; INSTALL httpfs; LOAD httpfs; INSTALL spatial; LOAD spatial;
ATTACH 'commons/pubdata' AS pubdata (TYPE iceberg, ENDPOINT 'https://public-catalog.lakehousebox.com', AUTHORIZATION_TYPE 'none');
SHOW ALL TABLES;

SELECT country_code, count(*) AS pharmacies
FROM pubdata.places.places
WHERE category = 'pharmacy'
GROUP BY 1 ORDER BY 2 DESC, 1 LIMIT 10;
Other Iceberg REST clients should attach the same way (endpoint https://public-catalog.lakehousebox.com, warehouse <handle>/<catalog>, no authentication); we have tested DuckDB. To publish your own catalog, see the public catalogs guide.